Computer Vision Project Library
From classical OpenCV to fine-tuned detectors, segmentation, 3D and foundation models. A CVPR paper reimplemented from scratch, a detector deployed 17× faster on an NPU, and the debugging stories behind each number.
19 projects · one benchmark each · laptop CPU + free cloud GPU
From classical OpenCV to fine-tuned detectors, segmentation, 3D and foundation models. A CVPR paper reimplemented from scratch, a detector deployed 17× faster on an NPU, and the debugging stories behind each number.
Stack: PyTorch · YOLO11 · OpenVINO · CLIP · SAM · OpenCV
The 19 projects
 01Live demo
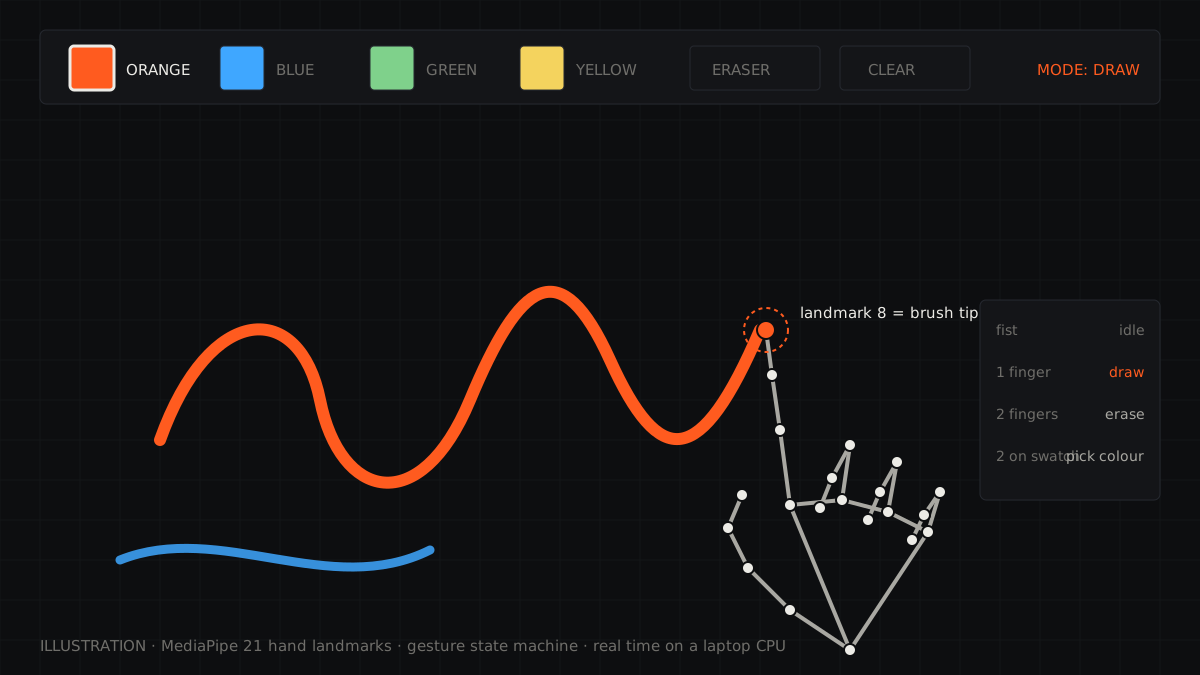
Virtual Painter
MediaPipe hand tracking, gesture state machine and a FastAPI live stream.
▶ Try it live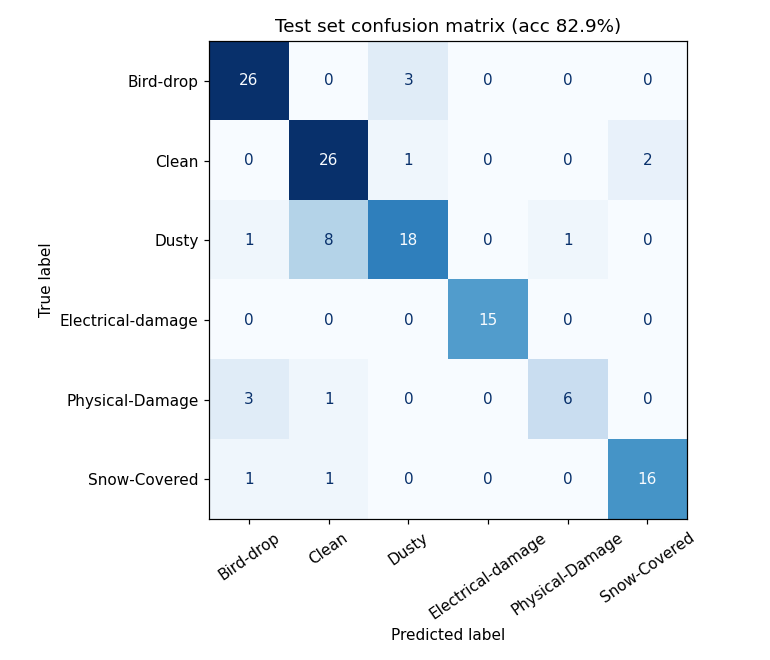 02
Solar Panel Defects
EfficientNet fine-tuned on CPU; Grad-CAM revealed the model partly looked at the roof, not the dust.
 03
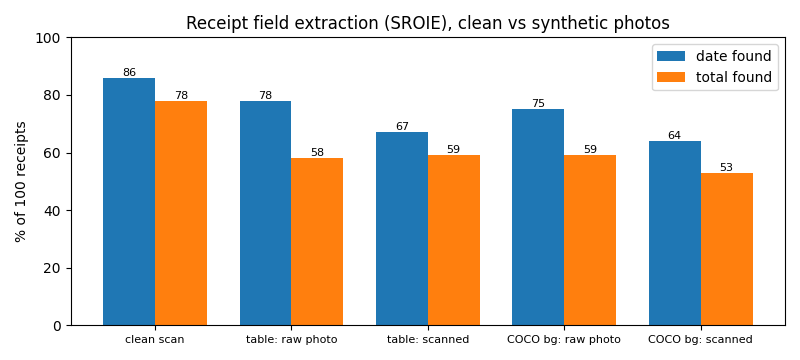
Receipt Scanner + OCR
Page detection and perspective warp in pure OpenCV, measured on synthetic phone photos with known corners.
 05
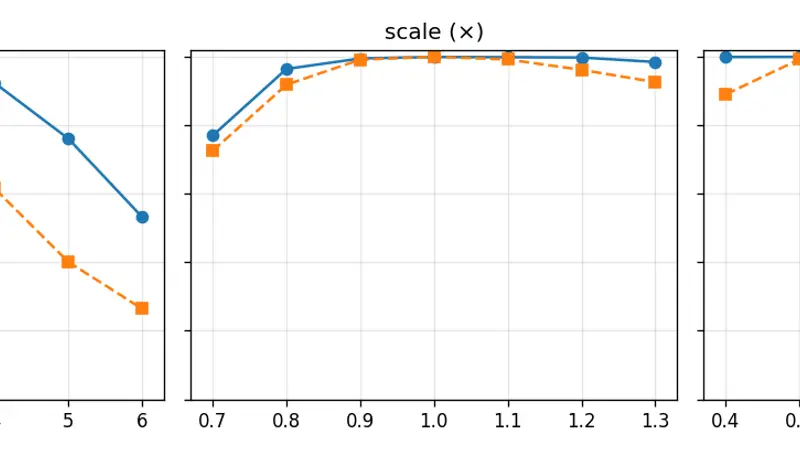
Sign Language Translator
A 100 % test set built from 1,704 photos; robustness curves show what a webcam does to it, and how augmentation helps except under blur.
 06
License Plate Recognition
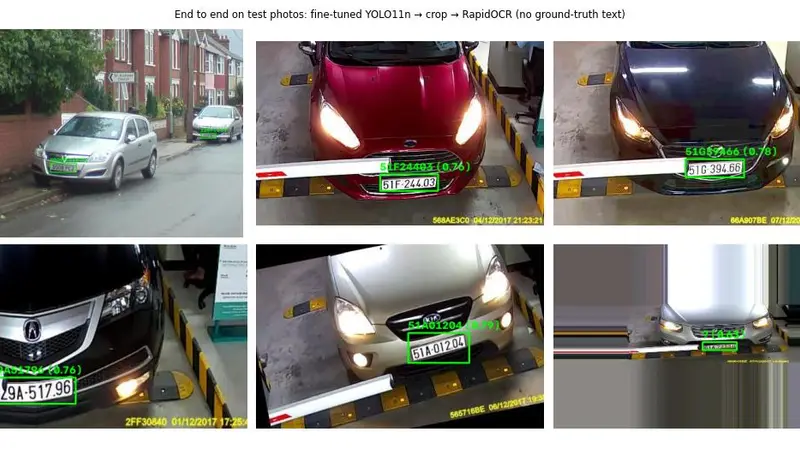
YOLO11n retrained on all 6,176 images on a free cloud GPU (mAP50 0.990) + OCR; a padding fix and plate-grammar rules took reading from 0% to 90%.
 07Live demo
PPE Safety Monitor
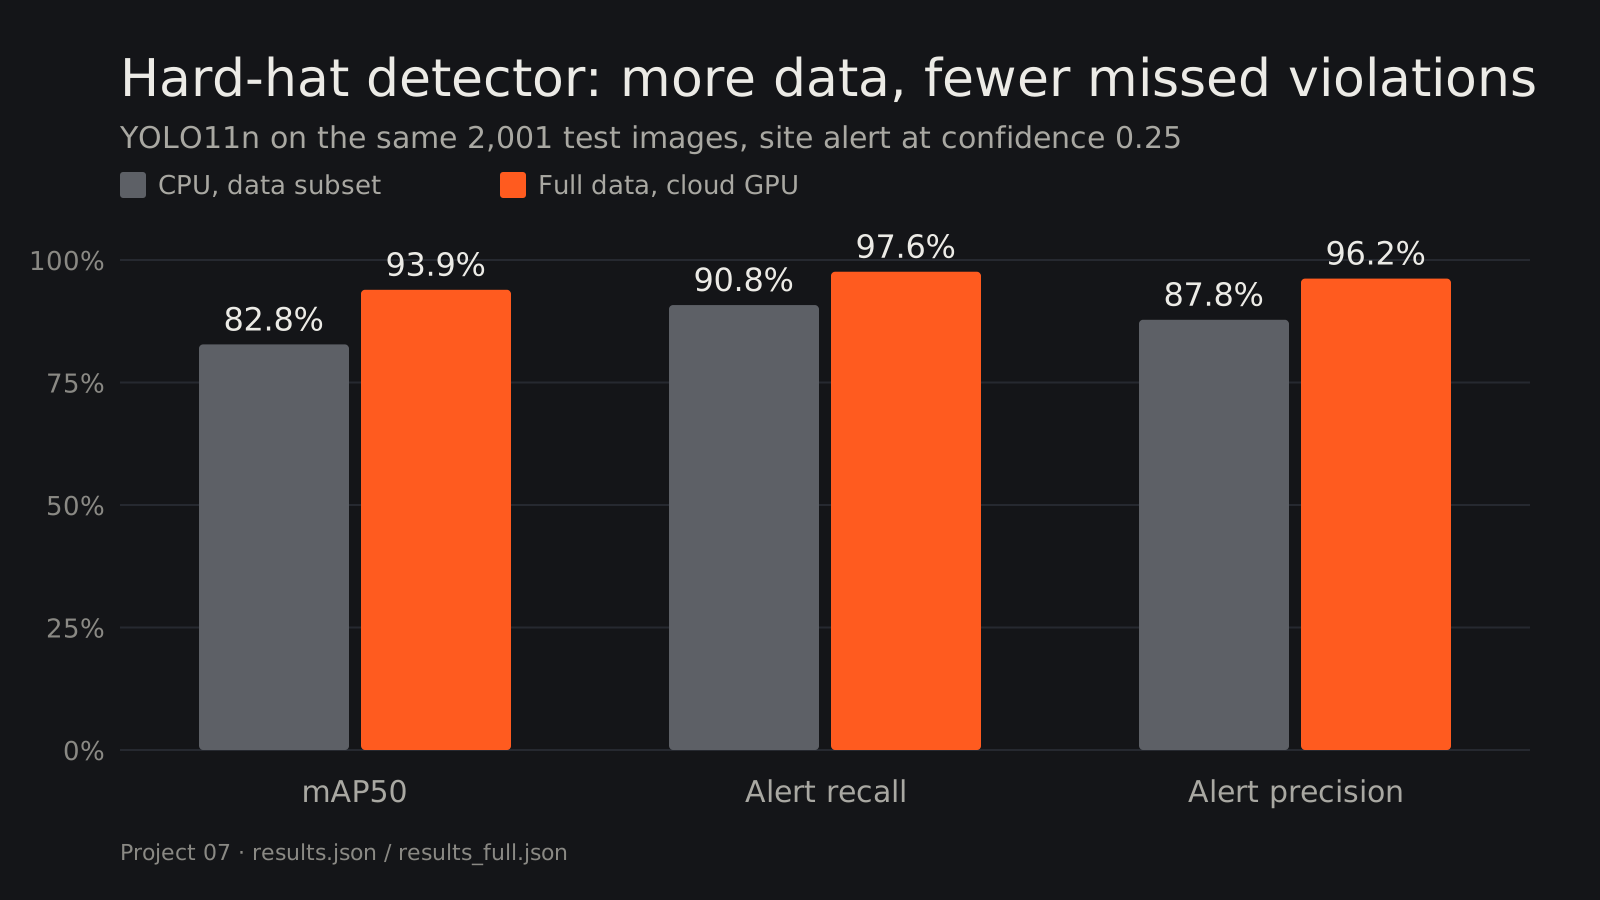
Hard-hat detector with alert-level metrics; retraining on all 13.8k images (Kaggle GPU) cut missed violations by 74 %.
▶ Try it live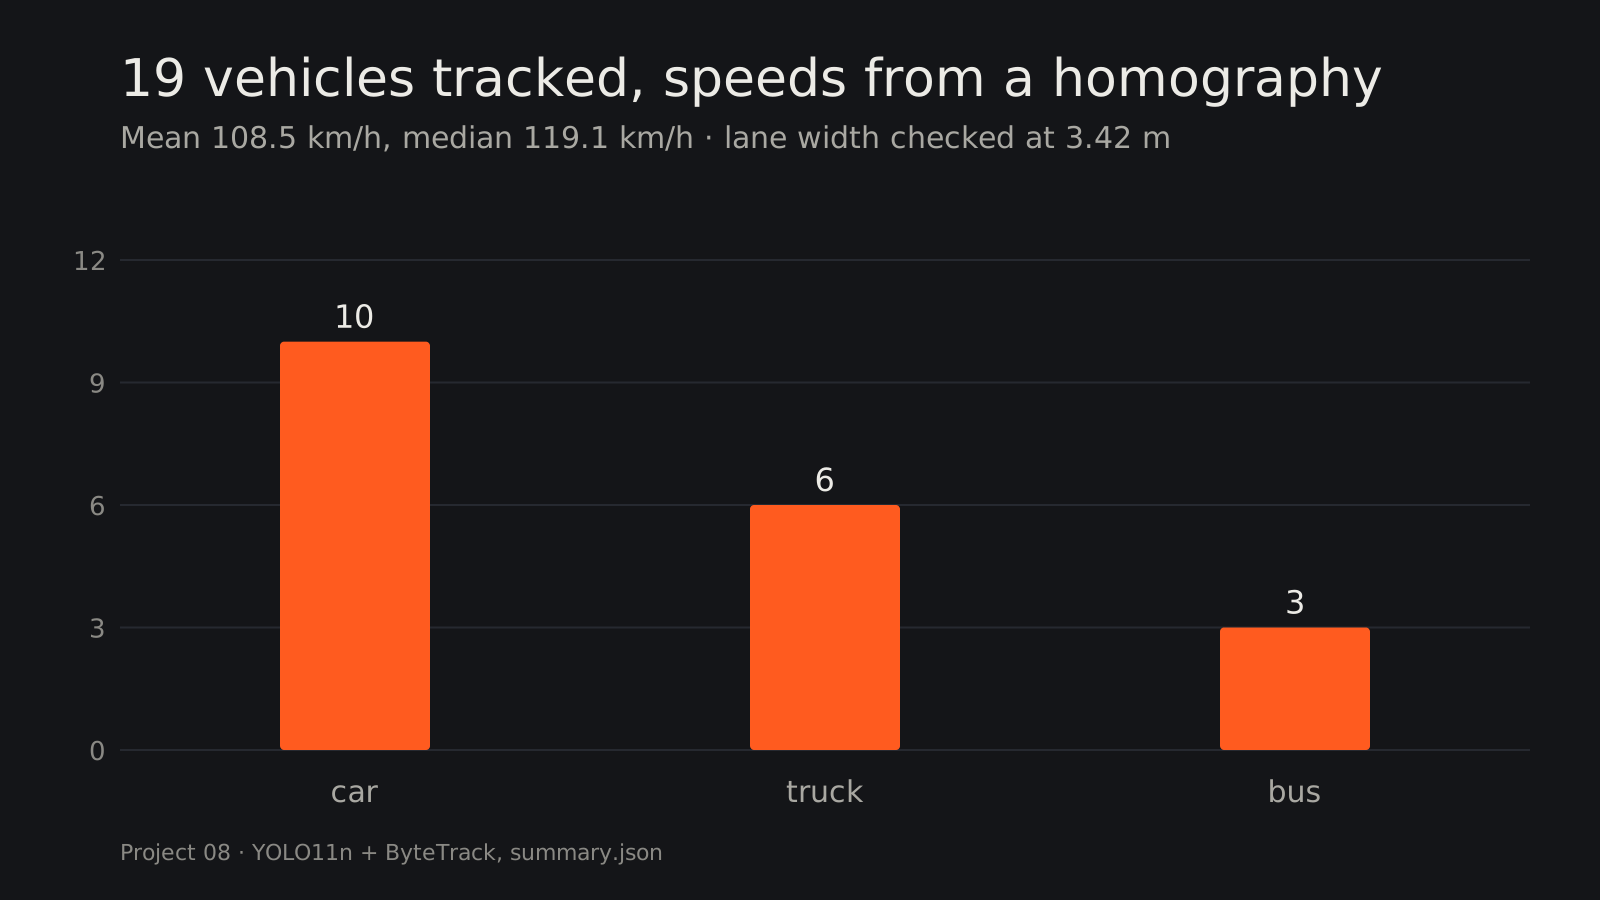 08
Traffic Analytics
Detection, ByteTrack tracking, line counting and bird's-eye speed estimation on a 4K highway video.
 09
Retail Shelf Monitor
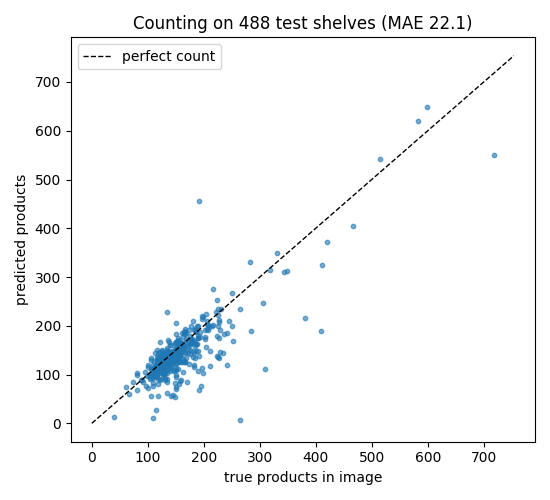
YOLO11n counts every product on dense supermarket shelves. Retraining on all 8,185 SKU-110K images on a Kaggle GPU raised mAP50 from 0.838 to 0.927 and cut count error from 13.3 % to 10.3 % on the same 488 test shelves.
 10
Face Verification
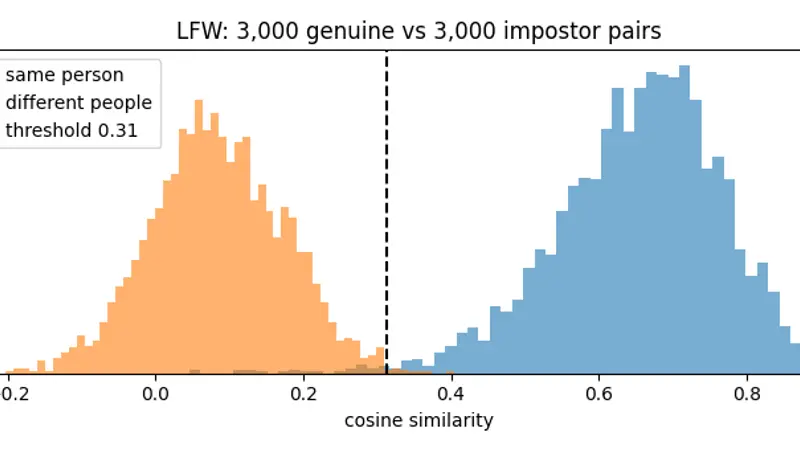
Alignment + embeddings + TAR@FAR, with a consent-based attendance tool and an explicit ethics & limits section.
 11
Polyp Segmentation
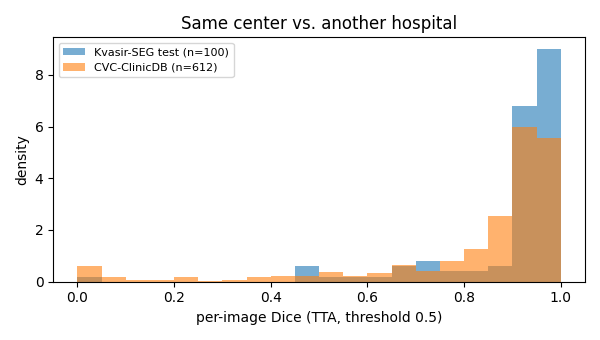
U-Net with a Dice + BCE loss, tested at a second hospital; a screening threshold catches 97 % of polyp pixels.
 12
Satellite Land-Cover
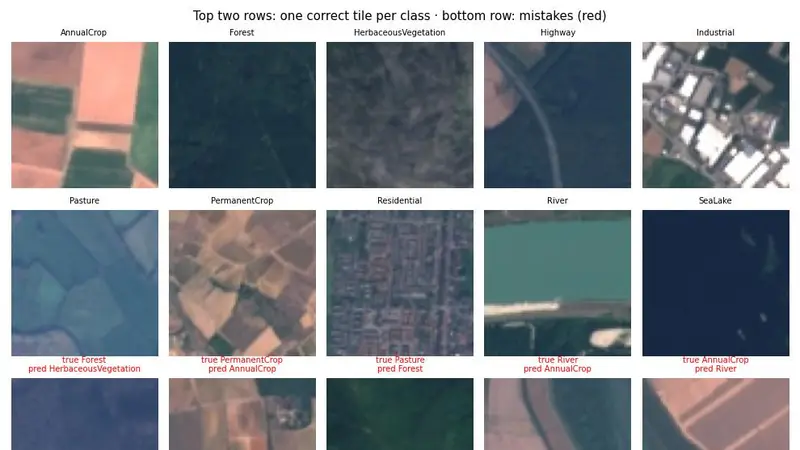
Why zero-shot fails on satellite tiles: a clear lesson in domain shift.
 13
PatchCore, from scratch
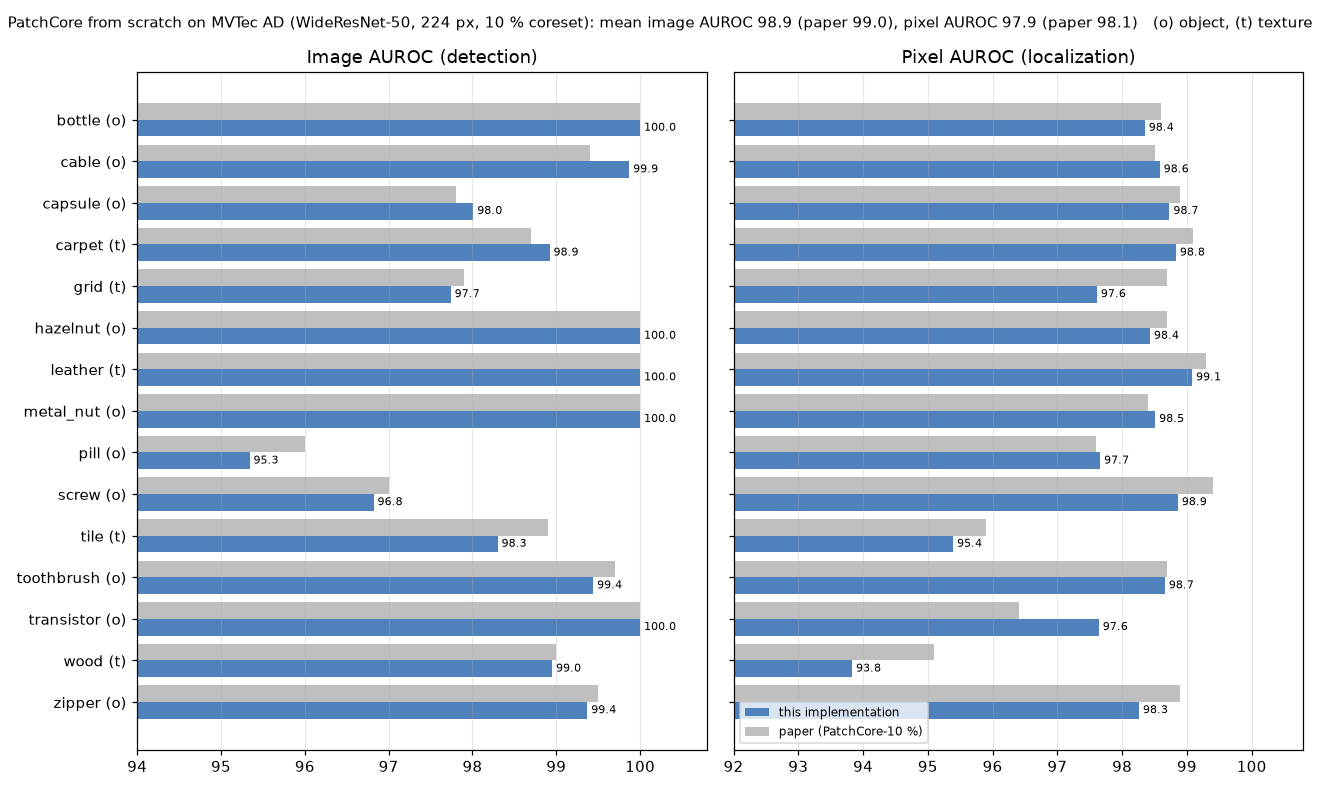
Reimplemented an industrial anomaly-detection paper in ~150 lines; finds defects without ever seeing one; 24 ms per image on a laptop iGPU, 36 ms on its NPU after working around a compiler bug.
 14Live demo
Human vs Machine 3D Vision
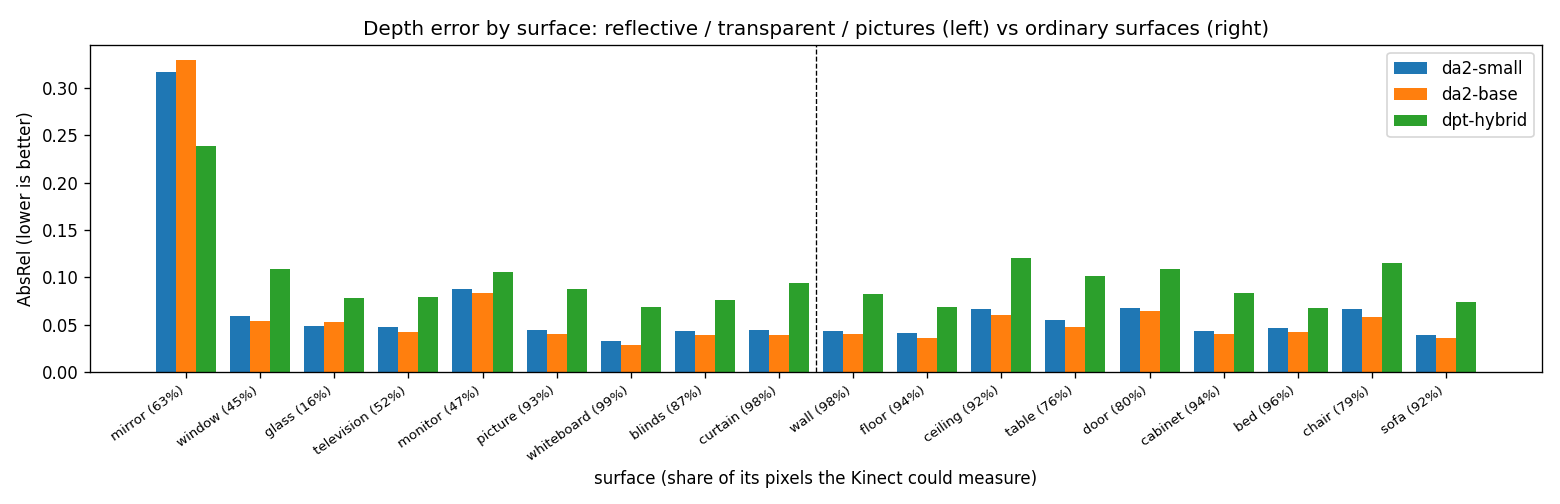
8 depth models on 5 datasets compared with human vision: where each fails (mirrors, hollow faces, framed photos, the camera's focal length), why, a mirror fine-tune that missed its target (−9 %, not −50 %), and a study you can play.
▶ Try it live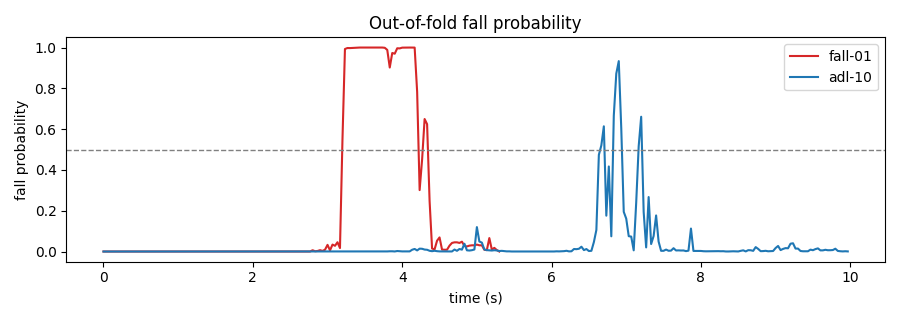 15
Fall Detection
Tells a fall from lying down on purpose using pose dynamics; threshold chosen by nested cross-validation grouped by video; trees beat a 1D-CNN and a GRU.
 16
Text-to-Image Search
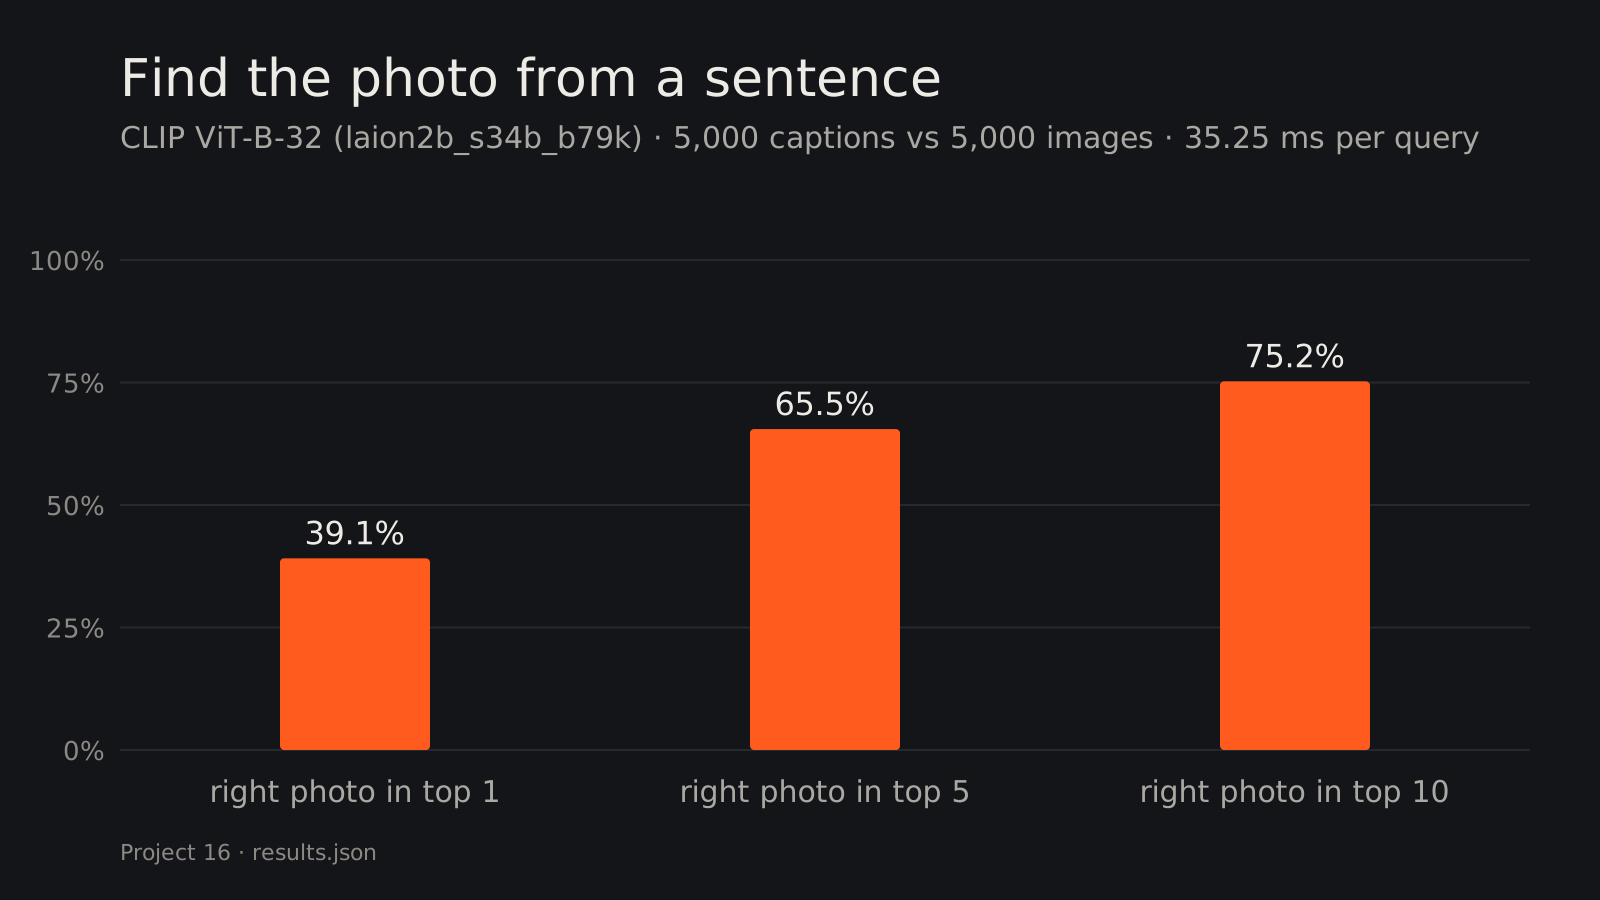
CLIP embeddings + FAISS: search photos by typing a description, with a web UI.
 17
Zero-Shot Auto-Labeling
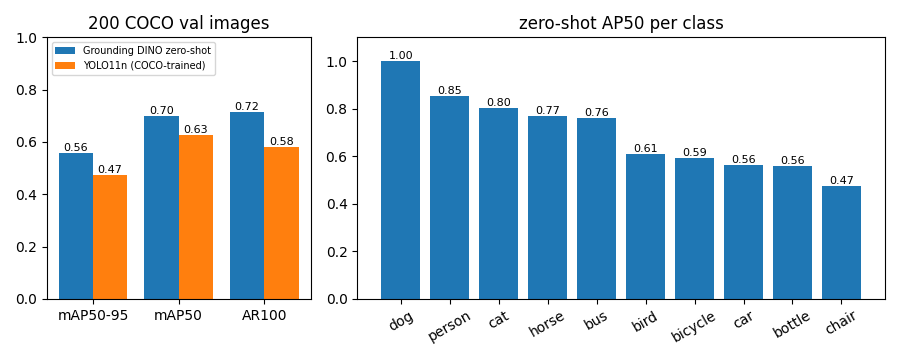
Grounding DINO + SAM label images from a text prompt and beat a COCO-trained YOLO, 118× slower.
 18
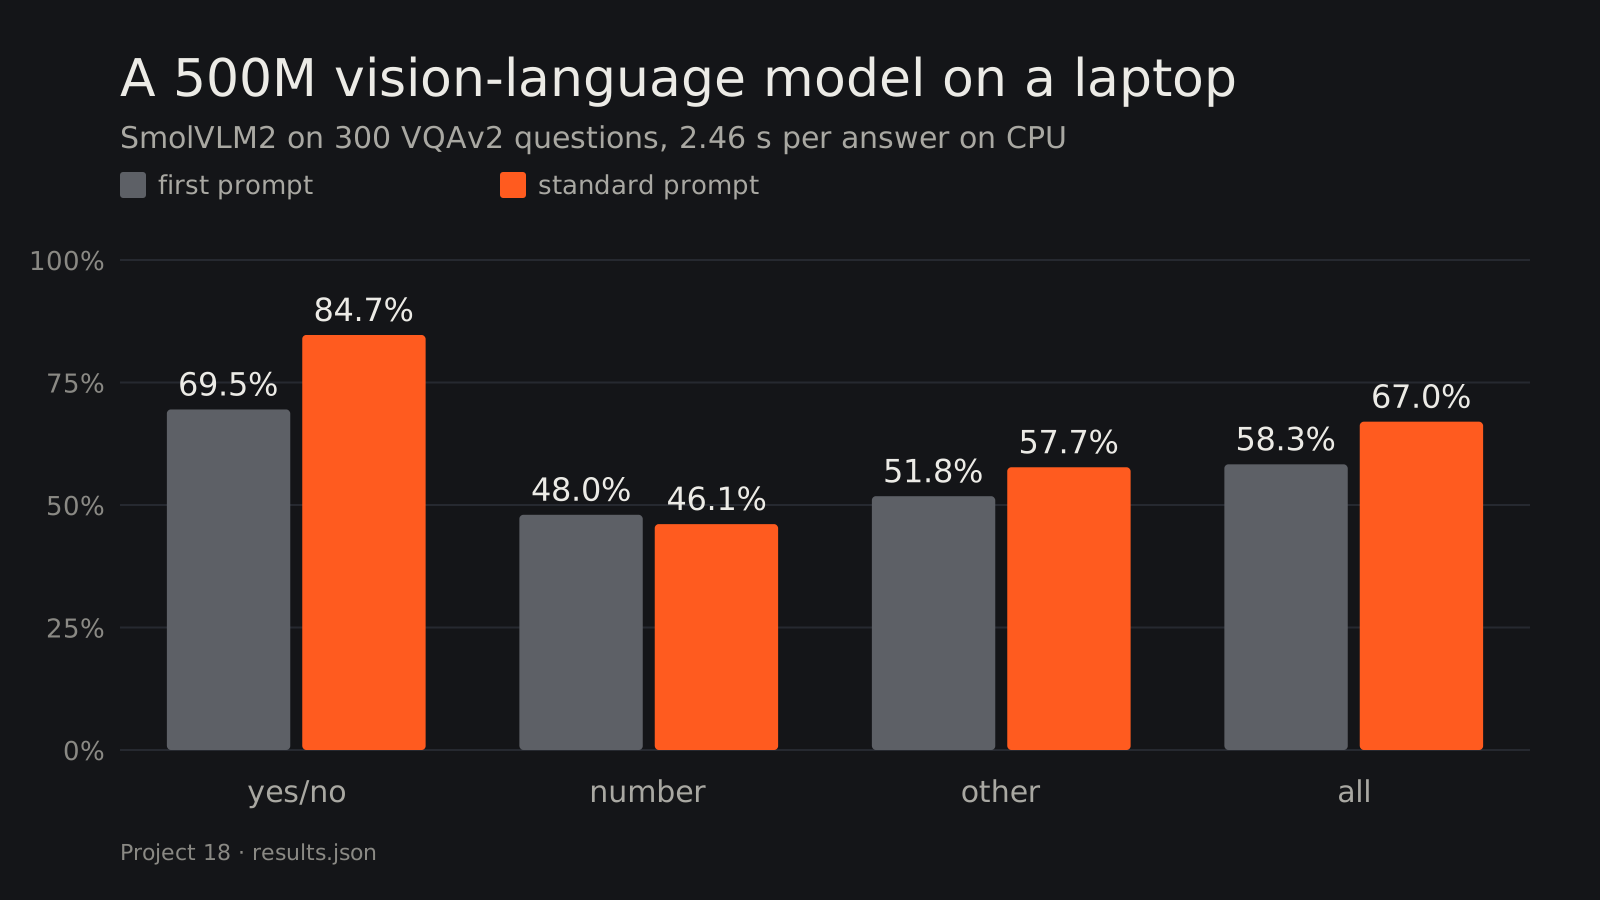
Image & Video Q&A
A local vision-language model on CPU (VQAv2 67%) and where it fails against a specialized pipeline.
 19
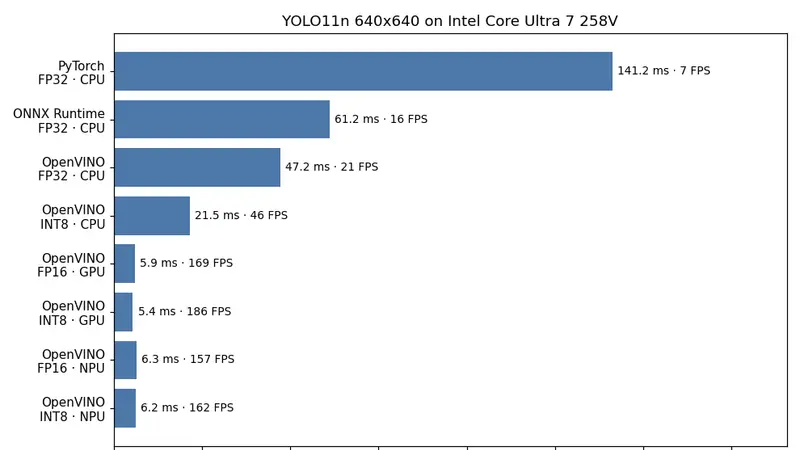
Edge Deployment Benchmark
PyTorch vs ONNX vs OpenVINO on CPU, iGPU and NPU, plus the hybrid-CPU threading trap I found along the way.
 20Live demo
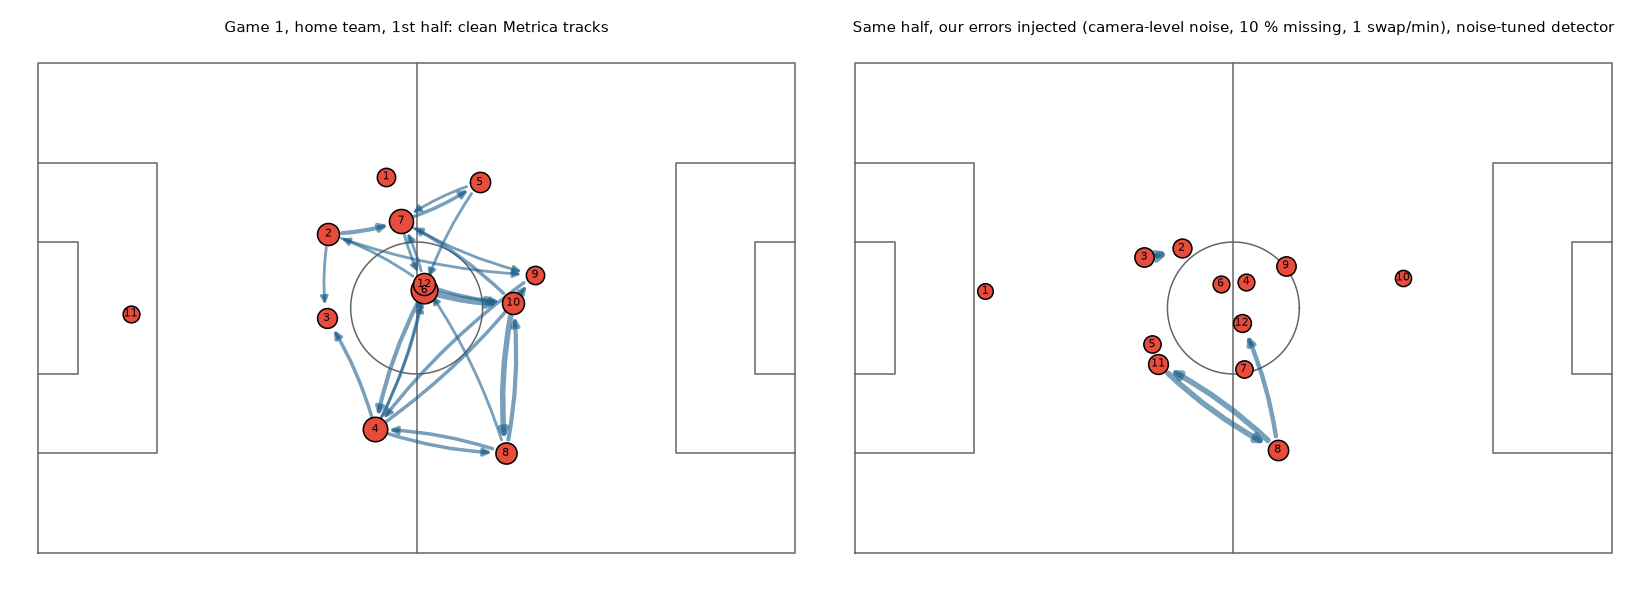
Football Analytics
Players, ball and teams from broadcast frames onto a top-down map, then an AI coach that ranks the passes on real Bundesliga tracking (pass-success AUC 0.77–0.84 on held-out matches).
▶ Try it live